
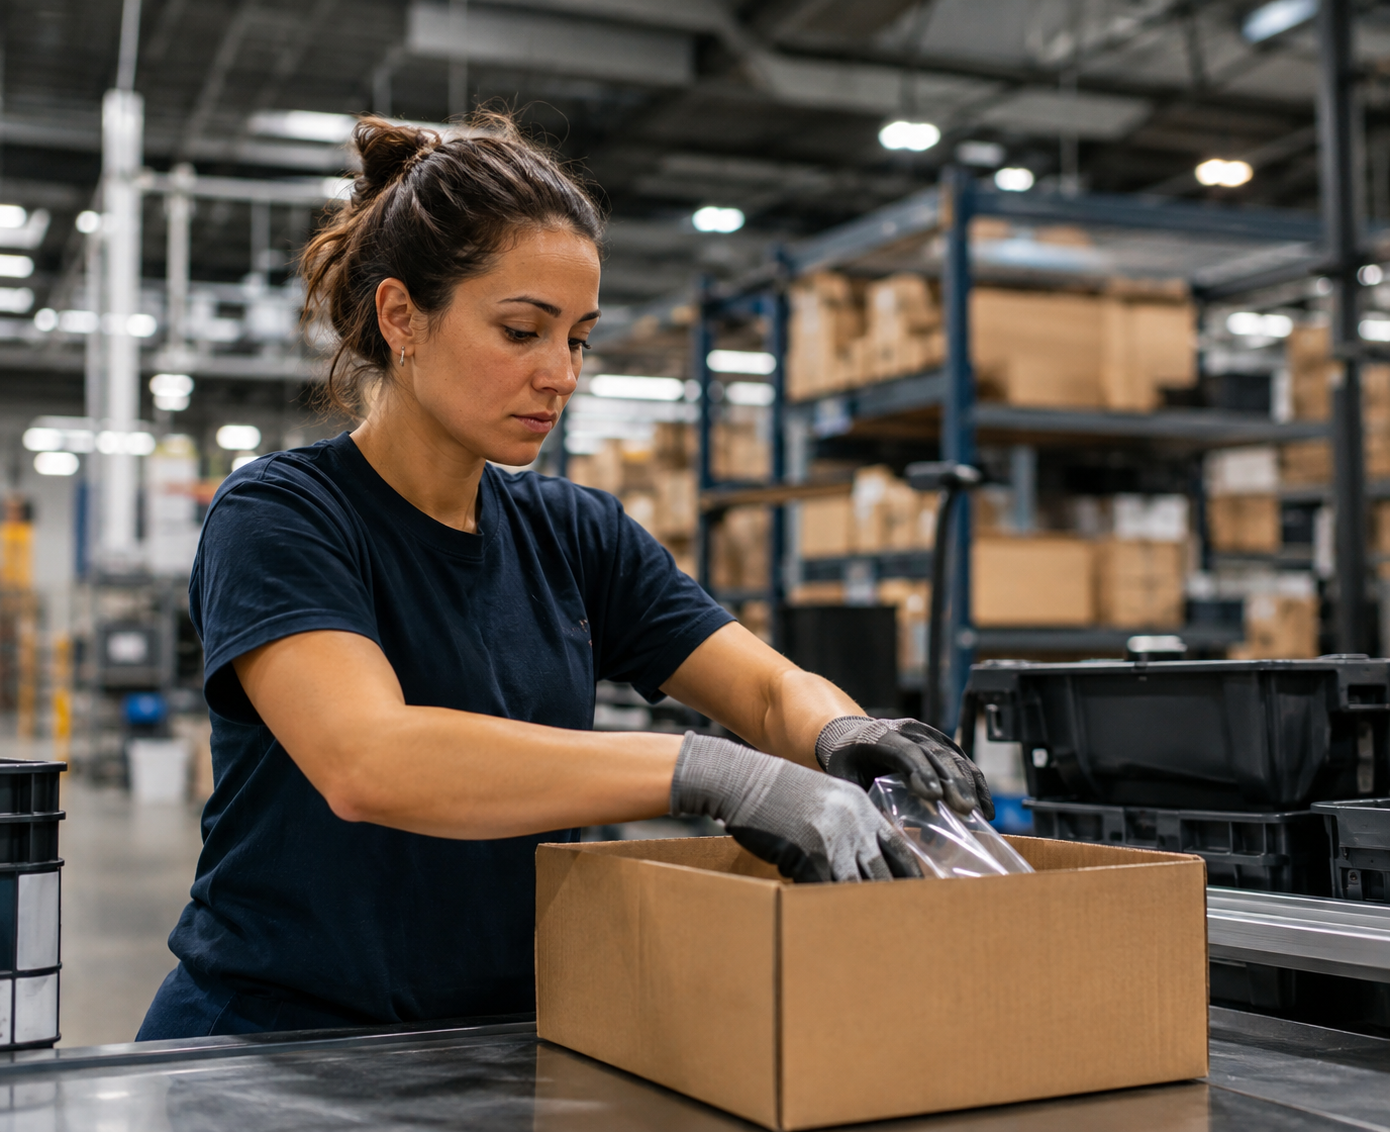
We capture high-quality human demonstrations of real-world tasks, combining synchronized video, hand and body motion, object interactions, and task context to support robotics, embodied AI, and multimodal learning.
What We Capture
We design expert demonstration programs that translate natural human workflows into consistent, structured datasets with the coverage, annotations, and quality controls required for model training and evaluation.
Multi-View Task Video
Hand, Body and Tool Motion
Object States and Interactions
Expert Procedures and Workflows
Task Phases and Event Labels
Success, Failure and Quality Metadata
94%
Demonstration Acceptance
Through clear protocols, operator training, representative sampling, and multi-stage review.Expert Human Demonstrations for Physical AI
100%
Time-Aligned Modalities
Video, pose, object interactions, audio, and task annotations aligned across every demonstration.Why Choose Our Human Demonstration Data Service?
Domain Expert Recruitment
We source and manage qualified participants or domain experts who can execute representative tasks safely and consistently.
Real-World Task Design
We tailor environments, objects, procedures, difficulty, edge cases, and capture methods to your target use cases.
Demonstration Quality Control
Automated checks and trained reviewers identify missing steps, visibility issues, inconsistent execution, and annotation errors.
Diverse, Scalable Coverage
We scale across participants, environments, task variants, geographies, and operating conditions while maintaining one quality standard.
Frequently Asked Questions
What is human demonstration data?
Human demonstration data records people performing real-world tasks so models can learn actions, procedures, interactions, and context.
What types of tasks can you collect?
We support household, industrial, logistics, retail, office, tool-use, assembly, maintenance, and other project-specific workflows.
Can you recruit domain experts?
Yes. We can recruit and manage qualified participants or experts based on experience, location, language, and task requirements.
Which modalities can be captured?
We can capture multi-view video, egocentric video, hand or body pose, audio, object states, device telemetry, and custom sensor streams.
How do you ensure demonstration consistency?
We use detailed protocols, operator training, calibration examples, acceptance criteria, and multi-stage review.
Can you include rare cases and failures?
Yes. We can deliberately sample edge cases, mistakes, failures, recovery behavior, and task variations with structured labels.
Do you provide annotations?
Yes. We can provide task boundaries, action phases, objects, tools, outcomes, key events, natural-language descriptions, and custom labels.
How is the data delivered?
We deliver raw and processed media with synchronized metadata in JSON, CSV, HDF5, LeRobot, RLDS, or custom formats.