
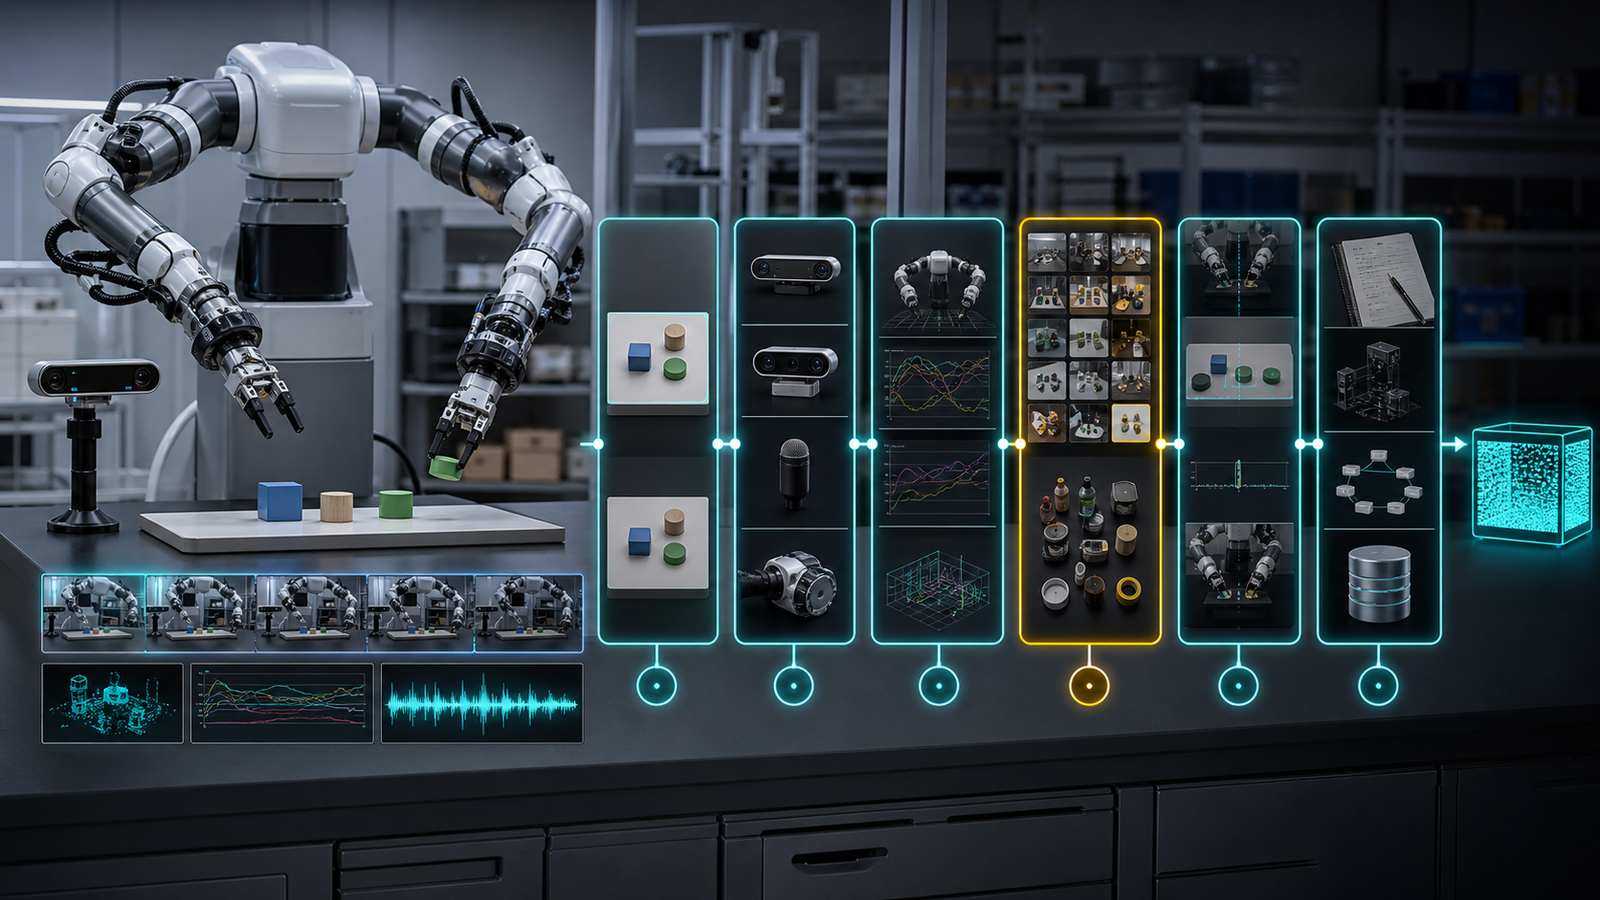
Robot demonstration data is training-ready when the task outcome is valid, sensor streams are intact and synchronized, actions and states are interpretable, episode boundaries are correct, required variations are covered, and the dataset is documented well enough to reproduce its use. A video that “looks good” is only one part of that standard.
Embodied AI datasets combine physical execution with software instrumentation. Quality failures can enter through either side: the operator performs the wrong task, or the correct task is recorded with missing frames; the robot succeeds, but the instruction is wrong; the stream is complete, but the camera calibration changed halfway through the shift.
That is why acceptance needs separate tests for semantics, signals and coverage.
The TRACED acceptance framework
We organize acceptance around six questions: Task, Recording, Action-state, Coverage, Episode and Documentation—TRACED.
T — Task correctness
Did the demonstration execute the intended task under the specified conditions?
- The initial state matches the task definition.
- Required objects and tools are present.
- The operator follows permitted strategies.
- The end state meets a measurable success rule.
- Safety or exclusion rules were not violated.
Success should be operational. “Place the mug in the tray” is ambiguous until the specification defines the tray region, acceptable orientation, collision rules, time limit and whether regrasping is allowed.
R — Recording integrity
Are all required files readable, complete and associated with the correct episode?
- Expected modalities are present.
- Frame rates and resolutions fall within tolerance.
- Dropped, duplicated and corrupt frames are detected.
- Timestamps are monotonic and expressed in known units.
- Calibration version and device identifiers are recorded.
Automate these checks. Human reviewers should spend attention on semantic ambiguity, not discover that a video file is empty.
A — Action-state consistency
Do the action and state channels mean what the schema says they mean?
Verify coordinate frames, units, joint order, quaternion convention, gripper encoding and whether actions are absolute targets, deltas, velocities or commands after controller filtering. Plot the signals. Replay a sample when possible. A silent unit mismatch can pass file validation and still ruin training.
C — Coverage contribution
Does the accepted episode fill a planned cell in the collection matrix?
Coverage should be measured across variables that matter at deployment: object identity and geometry, scene, lighting, clutter, start pose, camera placement, operator, motion strategy and outcome. BridgeData V2 was deliberately collected with variation in objects, camera pose, workspace positioning and environments; its 53,896 trajectories demonstrate why diversity is a dataset design choice, not a by-product.
E — Episode boundary quality
Does the episode begin before the relevant decision and end after the outcome is observable?
Over-trimmed episodes remove context. Under-trimmed episodes waste sequence length and may include unrelated resets. Boundary rules should handle aborted attempts, pauses, human intervention and multi-stage tasks explicitly. Store subtask events when long-horizon behavior will be trained or evaluated.
D — Documentation and lineage
Can another engineer understand where the data came from and how it changed?
The Datasheets for Datasets work argues for transparent documentation of dataset motivation, composition, collection and recommended use. For robot data, add hardware configuration, control interface, calibration, environment taxonomy, QA rules, transformations, known limitations and version history.
Use three levels of acceptance
A single pass/fail flag wastes information. Use at least three levels:
- Accepted for positive training: meets task and signal requirements.
- Accepted for diagnostic or recovery use: contains a failure, intervention or partial trajectory with valid recording.
- Rejected or quarantined: corrupted, ambiguous, outside specification or unsafe.
This protects the expert set without deleting useful evidence about failure states.
Separate objective checks from expert judgment
Objective checks include file presence, duration, sample count, timestamp monotonicity, resolution, signal ranges and checksum validation. Expert checks include task validity, motion quality, ambiguity, recoverability and whether an unconventional strategy is acceptable.
The division matters for scale. A rule-based gate can process every episode. Expert review can then focus on a statistically meaningful sample plus automatically flagged anomalies. This reduces cost and makes quality decisions more consistent.
Measure inter-reviewer agreement
If two trained reviewers repeatedly disagree on success, the problem is usually the specification, not the people. Double-review a calibration set before production, discuss disagreements and rewrite vague rules. Continue sampling agreement during collection, especially after tasks, hardware or operators change.
A review guide should include positive examples, near-boundary examples and clear rejection cases. “Use common sense” is not a quality standard.
Quality is model- and task-dependent
A demonstration can be physically successful yet poor for a specific learning objective. A policy trained for smooth industrial execution may not benefit from highly variable operator strategies. A generalist model may value that variation. Research on data quality in imitation learning frames quality through distribution shift: a high-quality dataset should help keep the learned policy within supported states at test time.
Therefore, acceptance criteria should come from the intended model input, action representation and deployment environment—not from a generic checklist copied from another project.
A delivery report buyers can use
For each dataset version, request:
- captured, accepted, diagnostic and rejected episode counts;
- rejection reasons and trends by device, operator and task;
- coverage tables for planned variables;
- signal-integrity and synchronization statistics;
- reviewer agreement on sampled episodes;
- schema, units, coordinate frames and label definitions;
- known limitations and recommended exclusions;
- a machine-readable manifest with dataset lineage.
MovraWorks builds these controls into human demonstration data collection and robot-data programs from the pilot stage. Acceptance is not a final inspection after the budget has been spent. It is the mechanism that keeps collection pointed at the training objective.